It re-asks for information the user already gave
Frustration, and an abandoned session
New research from Maximem. Agentic Context Management: Solving Agent Memory and Cost by Treating Them as Lifecycle and Architecture ProblemsAgent Memory is an architecture problem. Read the paper →
Agentic Context Management
Persistent memory and context for AI agents, across all popular agent frameworks.
No credit card required. Google or GitHub sign-in.
01Forgetting
02The alternatives
Every one of these is a workaround for a missing layer.
03The three layers
Organisational · Shared across your users and your tenants. Your policies, your product facts, your pricing. Company knowledge rather than personal knowledge.
Long-term · Persists across sessions, per person. The layer a user means when they say it remembers me.
Short-term · The current session. Working memory.
Most memory tools give you the session. The value is in the two above it.
04The product
Memory is not a storage problem alone. It is an active context-management problem.
You send Synap the conversation as it happens. Before your agent replies, you ask what is known about this person, and you get back a short, ranked set of facts, formatted and ready for the prompt. Two calls. Writes return immediately and never block your agent.
No vector database to run. No extraction pipeline to build. No retrieval ranker to tune. No scoping logic to get right. Those are the product.
Python and TypeScript SDKs, a REST API from any language, a hosted MCP endpoint, and native adapters for 23 agent frameworks.
05What you get
Structured capture and entity resolution.
Customer and client scopes.
Validated compaction.
Anticipatory retrieval.
06How it works
A conversation turn does not land in a database. It runs through a pipeline that turns raw dialogue into structured, scoped memory, governed by an architecture generated for your specific agent. The write call returns before any of that happens; everything after runs behind it and never blocks your agent. On the read side, most reads never leave your process: context is pre-fetched while the conversation is still going.
Scroll the diagram sideways to follow the full path →
07The job
It stays true
Your agent stops repeating what stopped being true, and nothing is lost getting there.
Conscious and Lossless Forgetting · Provenance · Consolidation
It stays fast
Context arrives before the agent asks, and a bad day for one part is not an outage.
Anticipatory Retrieval · Resilient Retrieval · Agentic Compaction
It stays yours
Isolated by default, configured to your posture, deployable where you need it.
Your hierarchy, not ours · Follows your PII posture · On-premise, self-hosted, and air-gapped options
It fits your agent
The memory architecture is generated for your agent rather than fitted to a one-size schema.
Custom Context Architecture · Entity Resolution · Native multi-format ingestion · Your organisation's context
08Three-tier consolidation
Meditation
Every few hours, a light pass
Nap
Once a day, deeper
Sleep
Your quiet hours: deep consolidation and conscious forgetting
09Scoping
A request sees its own level and every level above it. Never below. Never sideways. One person’s memory does not reach another person’s session, and one tenant’s does not reach another tenant’s.
Shared product knowledge, visible to everyone
Policies, team, and shared projects for this tenant
Facts, preferences, and episodes about this person
private to Alice
Policies, team, and shared projects for this tenant
Facts, preferences, and episodes about this person
private to Bob
When three levels is not your shape, define your own hierarchy at any depth, with the names you already use. How that works →
Out of the box
Or your own shape, at any depth
10Proof
Synap scores 92% on LongMemEval, the benchmark that tests whether a memory system retrieves the right fact from a long conversation and holds that accuracy as the conversation grows. In-conversation retrieval is under 15ms at P75. These numbers are a consequence of the architecture, not prompt tricks. The methodology is published and the eval harness is open source, so you can run it against any system you are evaluating.
| Synap | Mem0 | Zep | Supermemory | |
|---|---|---|---|---|
| LongMemEval | 92% | 73.8% | 71.2% (Zep's own figure; not run on our harness) | 71.3% |
| Entity resolution | Automatic, every tier | Pro tier only | Automatic | Fact extraction |
| Open-source eval harness | Full config published | No | No | No |
Measured on Maximem's open eval harness, same hardware, same prompts, same conversations, same scoring. Vendor self-reported figures differ and are shown separately. Zep has not been run on our harness, so its own published figure is shown instead. Full configuration and sources at /evals.
11Where it runs
Synap is not limited to a fixed list. It manages memory for customer support and sales agents, voice concierges, healthcare assistants, and multi-agent workflows alike. These are a few of the places teams run it today.
12Security and trust
Sensitive data
Your PII posture, applied per kind of data, down to what an individual API key is allowed to see, and a short list of things that are never stored for anyone.
Read the full posture →The full posture
Our full security posture is published in one place: data flow, hosting, encryption, retention, deletion, subprocessors, tenant isolation, and DPA availability.
Read the security and privacy page →Enterprise
Enterprise plans add VPC and private deployment, SSO and SAML, configurable RBAC, and custom SLAs.
See plans and enterprise options →Synap is Maximem's agentic context management layer for AI agents. It gives your agents persistent, cross-session memory with automatic entity resolution, temporal awareness, and anticipatory retrieval. Synap integrates natively with 23 frameworks (LangChain, LangGraph, LlamaIndex, OpenAI Agents, Pydantic AI, CrewAI, AutoGen, Google ADK, Haystack, Agno, Semantic Kernel, Microsoft Agent Framework, NeMo Agent Toolkit, LiveKit Agents, Pipecat, Claude Agent SDK, Mastra, Vercel AI SDK, Vercel eve, Strands Agents, CAMEL-AI, Smolagents, and deepagents) and scores 92% on the LongMemEval benchmark and 93.2% on LoCoMo. Free tier available with no credit card required.
Synap offers native SDK integrations for 23 agentic frameworks: LangChain, LangGraph, LlamaIndex, OpenAI Agents, Pydantic AI, CrewAI, AutoGen, Google ADK, Haystack, Agno, Semantic Kernel, Microsoft Agent Framework, NeMo Agent Toolkit, LiveKit Agents, Pipecat, Claude Agent SDK, Mastra, Vercel AI SDK, Vercel eve, Strands Agents, CAMEL-AI, Smolagents, and deepagents. Install the SDK, configure your API key, and start managing context with a few lines of code. Most developers are up and running in under 5 minutes. Visit docs.maximem.ai for the Quickstart guide, SDK reference, and framework-specific integration examples.
Synap provides Python and TypeScript/JavaScript SDKs, plus a REST API that works with any language. The SDK includes native wrappers for 23 agentic frameworks, a hosted MCP endpoint for no-code platforms, and a CLI. Visit docs.maximem.ai for the latest SDK availability, language-specific guides, and API reference.
Synap manages memory through customized memory architectures built for each use case. It handles ingestion (deciding what to store), retrieval (surfacing the right context at the right time, including anticipatory pre-fetching, under 15ms at P75 in-conversation), entity resolution (linking references like "my manager" and "Sarah" across sessions), temporal awareness (weighting recent context higher than stale context), and conscious forgetting (processing retractions and contradictions). A change never destroys the previous version, so every memory can be traced. All of this happens automatically without the agent needing to manage its own memory.
Yes. Synap encrypts data at rest, keeps tenant data strictly isolated, and is architected for compliance review. Enterprise plans include VPC/private deployment options, SSO/SAML, configurable RBAC, custom SLAs, and dedicated customer success management. Synap also supports BYOK (Bring Your Own Key) so you can use your own AI model provider credentials. Contact [email protected] for enterprise pricing and security documentation.
Synap takes a different architectural approach. Where Mem0 applies a universal memory model (extracted facts plus embeddings), Synap builds customized memory architectures per use case. Where Zep is built around a temporal knowledge graph (Graphiti), Synap focuses on anticipatory retrieval and latency optimization. On the LongMemEval benchmark, Synap scores 92% accuracy and 93.2% on LoCoMo, measured on an open-source harness anyone can reproduce. Synap also supports 23 agentic frameworks natively (LangChain, LangGraph, LlamaIndex, OpenAI Agents, Pydantic AI, CrewAI, AutoGen, Google ADK, Haystack, Agno, Semantic Kernel, Microsoft Agent Framework, NeMo Agent Toolkit, LiveKit Agents, Pipecat, Claude Agent SDK, Mastra, Vercel AI SDK, Vercel eve, Strands Agents, CAMEL-AI, Smolagents, and deepagents) and delivers in-conversation retrieval under 15ms at P75. Both Mem0 and Zep are solid tools. Evaluate all three against your own use case. Read the full Synap vs Mem0 comparison at maximem.ai/compare/maximem-synap-vs-mem0 and Synap vs Zep at maximem.ai/compare/maximem-synap-vs-zep.
Supermemory is multimodal-first with connectors for documents, images, videos, and URLs. Synap is conversation-and-agent-first. If you need to process diverse content types into a searchable memory layer, Supermemory covers that well. If you need the highest verified accuracy (92% on LongMemEval, 93.2% on LoCoMo) at low latency for multi-turn AI agents (customer support, voice AI, workflow agents), that is Synap's focus. Synap's architecture is built around anticipatory retrieval (under 15ms at P75, in-conversation), automatic entity resolution, temporal awareness, and conscious forgetting, which are capabilities specifically designed for agentic workloads rather than general-purpose document memory. Read the full Synap vs Supermemory comparison at maximem.ai/compare/maximem-synap-vs-supermemory.
The SDK and the benchmark eval harnesses are open source, available on GitHub at https://github.com/maximem-ai/maximem_synap_sdk. You can self-host the full stack; we support it, it is just not out of the box. The managed cloud runs the engine, and adds the dashboard, analytics, and a free tier with no credit card required.
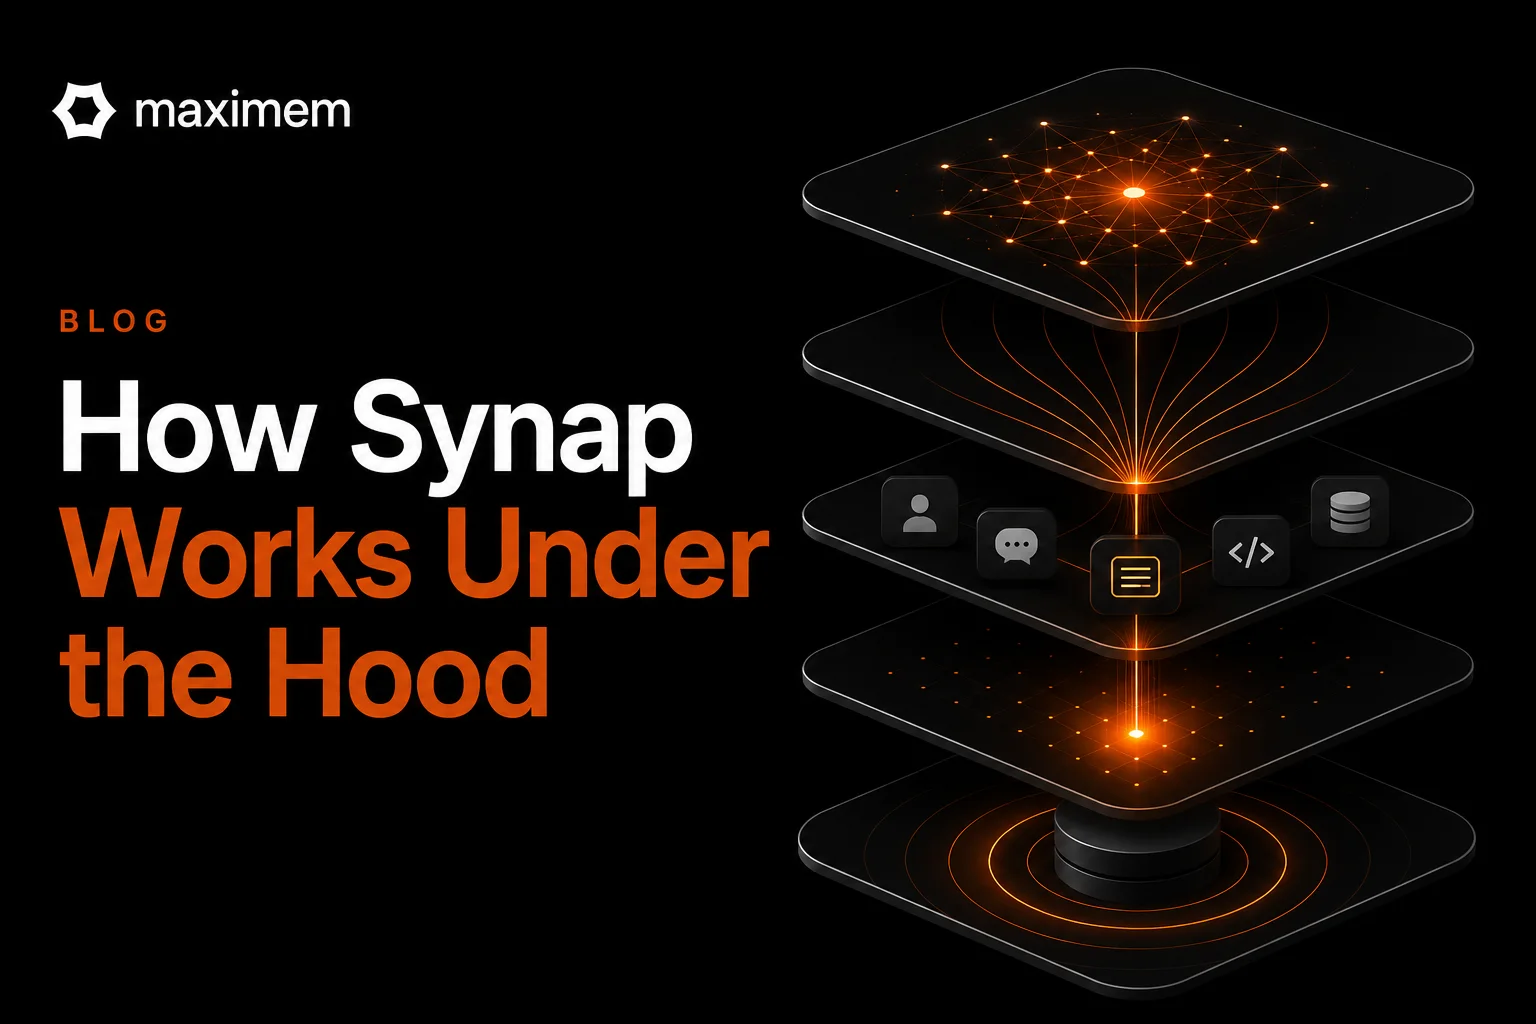
We launched Maximem Synap today. Here's a peek into how it is built.
Synap updates: 92% LongMemEval (up from 90.2%), 93.2% LOCOMO, 17 framework integrations, a browser playground, public pricing, and a free accuracy eval on your own agent.
AI agents don’t fail from lack of memory, they fail because context doesn’t evolve. This article shows why current approaches break, introduces the Context Management Trilemma, and how Synap enables agents to learn, adapt, and stop forgetting over time.
Get started
No credit card required. Google or GitHub sign-in.
Scoping call → eval on your data → trial. No card required.