Synap answers 95.6% of LongMemEval's 500 questions correctly, which is ahead of every published score from Mastra, Hindsight, Mem0, Zep and Supermemory. Today we are open-sourcing the architecture behind that number as Synap Core: the Synap memory engine as a server you run on your own machine, under Apache 2.0, started with one docker compose up.
Getting to that score was never about a bigger vector index. It came from treating memory as a pipeline that decides what a conversation means before anything is stored, and that pipeline is the part we have put in the open.
Why agents forget the wrong things
Every LLM call is stateless, so whatever an agent remembers between conversations, somebody built on top of it. Most memory layers do that by storing chunks of text and searching them, which works in a demo and breaks in the first week of real use, in two ways.
A user says "my manager" on Monday and "Sarah" on Thursday. A chunk store sees two unrelated strings, so the agent asking about Sarah never finds what was said about the manager. Then the same user mentions that the team now ships on Tuesdays, having said Fridays a month earlier. The chunk store returns both sentences with similar scores, and the model is left to guess which one is still true.
Neither failure is a retrieval problem. Both happen at write time, and no amount of clever search can fix a store that never worked out who a memory was about or which fact replaced which.
Resolve, then supersede
Synap Core turns conversations into typed memories (facts, preferences, events, episodes and emotions) and does two things to each one before it is stored.
First it resolves the entities. "My manager" and "Sarah" become one person across sessions and conversations, using synap-er, our open entity-resolution library. When the resolver is not sure, it holds the match for review instead of merging, because a wrong merge corrupts two people's memory at once.
Then it supersedes. Each new memory is compared with similar ones already stored and classified as a duplicate, an enrichment, unrelated, or a replacement. A replacement retires the old memory, so retrieval stops returning Friday the moment Tuesday arrives. Every memory also carries the period during which it held, so "last month" is stored as a date range your agent can reason over, not as two words.
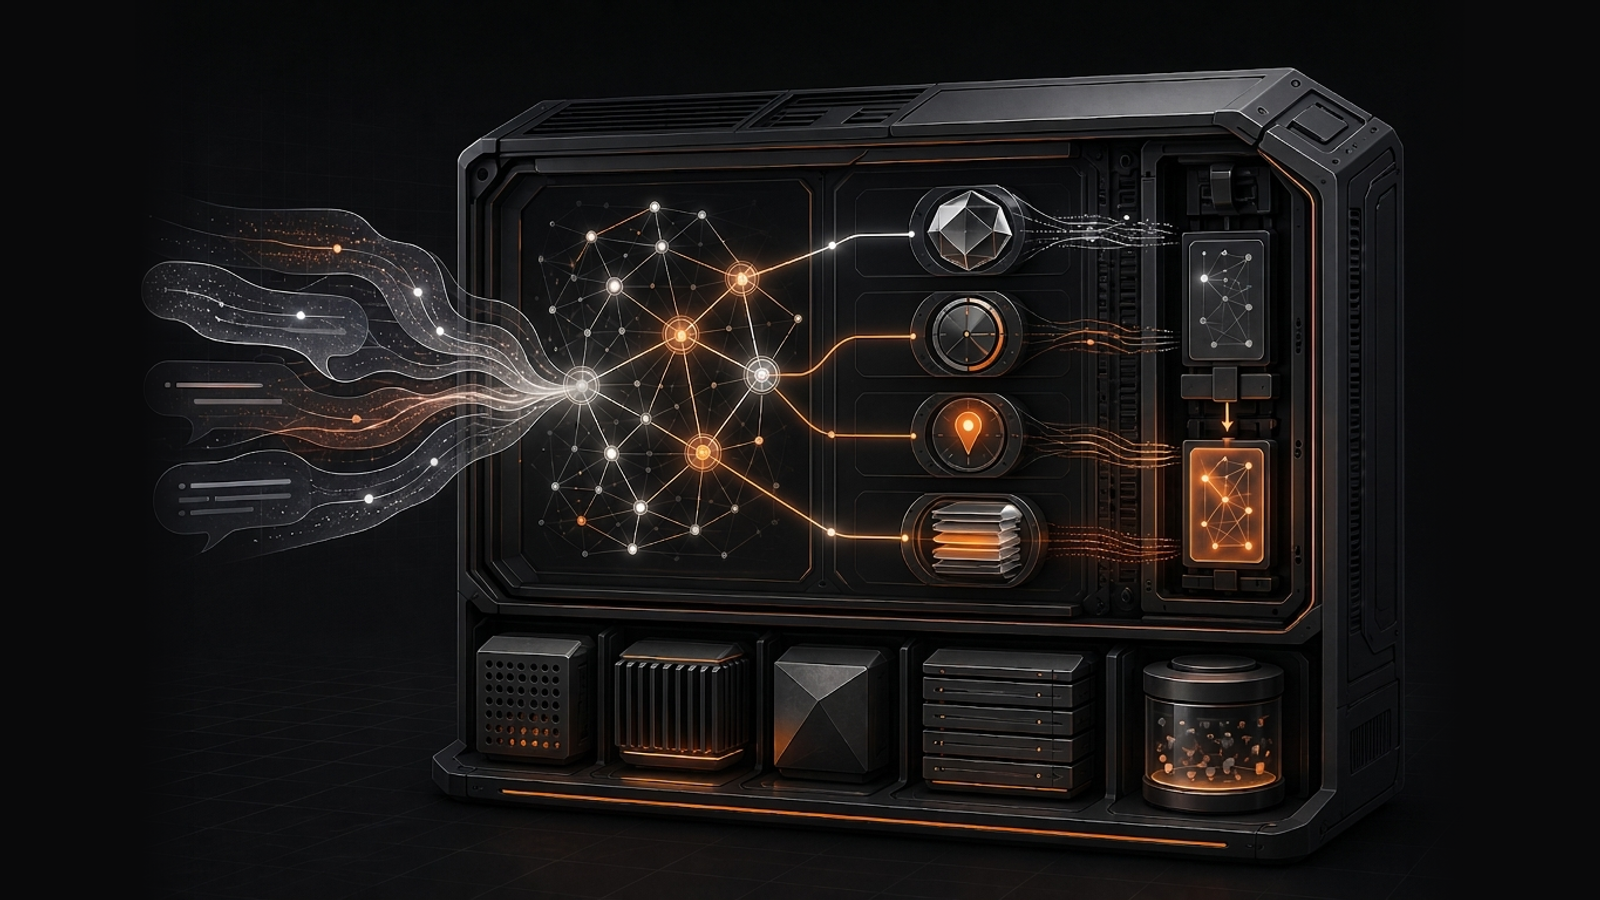
Retrieval then searches vectors, adds the knowledge graph when you ask for accuracy, and splits compound questions such as "X compared to Y" into parts. What comes back is a short list of current, attributed statements about the user, not a pile of transcript.
Your machine, your model, your data
One Compose file brings up the API alongside Postgres, ChromaDB, Neo4j and Redis, every image pinned by digest. Only the API is published, and only on localhost. There is no telemetry, and the README lists every outbound call the server can make.
You choose the model: OpenAI, Anthropic, Ollama, or anything that speaks the OpenAI API, such as vLLM. Embeddings run inside the server. With a local model, nothing about your users leaves your hardware.
What you remember, and how, is yours to decide as well. A single memory.yml sets the memory types, extraction guidance, ranking weights and scoping, and the server refuses to start on a mistake and names the line rather than ignoring it.
Same API as Synap Cloud
Core speaks the same API as Synap Cloud, so the same SDKs and the same integrations for 23 frameworks, including LangGraph, CrewAI, the OpenAI Agents SDK, Mastra and the Vercel AI SDK, work against both. Start on your own machine; if you later want the managed service, with authentication, multi-tenancy and tuning on production traffic, you change a base URL and add an API key. Your application code stays as it is.
Try it
Paste one prompt from the README into Claude Code, Codex or Cursor, and you are on the quickest route. The prompt installs a setup skill that checks your machine, waits while you put your model key in .env yourself, starts the stack and finishes by storing a memory and reading it back. The first start downloads about 2.3 GB of models once; after that the server runs offline.
Then point the SDK at it:
import asyncio
from maximem_synap import MaximemSynapSDK  # pip install maximem-synap

async def main():
    sdk = MaximemSynapSDK()  # reads SYNAP_BASE_URL=http://127.0.0.1:8000
    await sdk.initialize()
    result = await sdk.memories.create(
        document="User: I prefer dark mode.\nAssistant: Noted!",
        document_type="ai-chat-conversation",
        user_id="user_alice",
    )
    await sdk.memories.wait_for_completion(result.ingestion_id)
    context = await sdk.user.context.fetch(user_id="user_alice", search_query=["preferences"])
    print(context.preferences[0].content)  # "The user prefers dark mode."
    await sdk.shutdown()

asyncio.run(main())
What comes back is a statement about the user, not an echo of what they typed. That small rewrite is the whole idea at the smallest scale.
For anyone who wants to verify, the repo also publishes a full benchmark run of the self-hosted server, every answer included, so you can check exactly what you are running.
An agent that knows who it is talking to, and which of the things it was told are still true, stops making customers repeat themselves and gets better every time they come back. Synap Core puts that on your own disk. The code is at github.com/maximem-ai/maximem_synap_core, and we read every issue and discussion.