All articles
99 articles on AI memory, agent engineering and production AI, newest first.
Async Subagents: What the Orchestrator Keeps in Context, What Workers Hand Back, and What Should Outlive the Session
Async subagents let an orchestrator stay reachable while background workers run long tasks. What the orchestrator must keep about in-flight work so compaction cannot erase it, what a worker should hand back, when a follow-up should interrupt or enqueue, how results reach an orchestrator that is busy, idle or waiting on an approval, and which decisions and preferences should outlive the session, with LangChain Deep Agents, Claude Code and OpenAI behaviour as of 6 November 2026.
We Open-Sourced the Memory Engine Behind Synap
Synap scores 95.6% on LongMemEval, ahead of every published score from the major agent memory platforms, and today the architecture behind it is open source as Synap Core.
What Is a Company Brain? What It Is, What Memory It Actually Needs, and How to Test One
A company brain is a shared memory layer that pulls what a company knows out of Slack, Notion, meeting notes, docs and tickets and serves it to people and any AI assistant. Connectors and storage are the easy part. What it needs to be trusted: scoping (who may see what), time (when a fact was true), conflict handling when sources disagree, provenance and forgetting. A plain definition, what is in and out, an architecture checklist and a test plan.
Which LLM Should Write Your AI Agent's Memory? How to Choose and Test a Memory Extraction Model
Which LLM to use for memory extraction: in Mem0's October 2026 test of 17 writer models on LoCoMo, the writer alone moved accuracy from 84.1% to 93.5% and cost from $0.68 to $158.55 per 1,000 writes, yet the top six sat within 0.9 points. How to test writer models on your own transcripts, the failure modes to measure (rules written as memory, over-extraction, missed updates), and where a small judge model fits with a type-aware write policy.
Memory for Background Agents: Where It Lives When the Sandbox Is Discarded, What to Remember With No User in the Loop, and Who May Write or Forget
A background agent wakes on a cron, a heartbeat or an event, runs in a sandbox that is thrown away afterwards, and keeps only what it wrote somewhere else. Where that memory has to live (outside compute, scoped to the user and the agent, loaded at the start of every run), what to remember when no user is there to confirm anything, how async subagent results get written back without duplicates, and who may write to and delete from a memory several bots share.
Agent State vs Agent Memory: Why a Checkpoint Is Not Long-Term Memory, and How to Wire Both
Agent state is where one run or thread is: the checkpoint a LangGraph checkpointer, an OpenAI Agents SDK session or RunState, an ADK session or a Temporal event history keeps so the run can resume, pause for a human and replay. Agent memory is what the agent knows about a person or the world across threads: facts that get updated, scoped per user and deleted on request. What each framework gives you for each layer, the seven places teams confuse them, and a tested LangGraph build that wires both.
LLM API Pricing Comparison 2026: Every Major Provider per Million Tokens, Cached Input, and What a 40-Turn Conversation Costs
LLM API pricing compared as of 30 October 2026: the flagship and cheap model of OpenAI, Anthropic, Google, xAI, DeepSeek, Mistral, Moonshot, Alibaba, Zhipu, Groq, Fireworks and Together per million tokens, with cached input and cache-write rates, the three list prices that repeat across providers, the Gemini rises on 1 December and 1 January, and what the same 40-turn conversation costs on every model, from $0.016 on Qwen3.7-Flash to $5.46 on GPT-6 Astra and Claude Fable 5.1.
Context Compaction vs Retrieval: When Summarising a Long Agent Session Is Cheap, When Exact Lines Win, and What Neither Does Across Sessions
Compacting a 400,000-token Claude Opus 5.5 session costs about $0.08 of input when the prompt cache is warm and $1.60 to $2.00 when it has expired, at list prices as of 30 October 2026. Mainplane's measurement, Claude Code's and OpenAI's compaction docs, when to compact and when to start fresh and retrieve exact lines from the old session file, and the cross-session problem neither approach solves.
Memory Write Policy for AI Agents: What to Remember, When to Overwrite, When to Ask, and What Never to Store, by Memory Type
A memory write policy decides, before anything persists, whether an AI agent may store a candidate memory, and the rules have to differ by type: facts supersede with history, preferences need a direct statement, values and beliefs need the highest bar and a confirmation, instructions may only come from the user or operator, and episodes append and expire. A policy table, the evidence for per-type thresholds, and a tested Python write gate.
Ontology for Agent Memory: Glossary, Taxonomy or Ontology, and How Much Schema an Agent Needs
Agent memory borrows three layers from data architecture: a glossary of definitions and aliases, a taxonomy of memory categories and an ontology of typed relationships. Definitions alone lifted extraction F1 from 0.42 to 0.57 in one 2026 study, while a typed ontology pays off on set, negation and supersession questions. How ontologies constrain extraction and entity resolution in Zep, Cognee and LangChain, which layer you need at which scale, and what over-modelling costs.
OpenRouter Pricing 2026: Credit Fees, BYOK, Free Model Limits, and What Routing Costs Next to Going Direct
OpenRouter pricing as of 29 October 2026: model tokens at the provider's list price, a 5.5% fee on credit purchases on Standard ($0.80 minimum by card) and 8% on Business, BYOK free up to $25,000 of list-price inference a month and 5% after that, free models at 20 requests a minute and 50 or 1,000 a day, and what a 40-turn conversation costs through OpenRouter next to going direct to Anthropic, Google, DeepSeek, Mistral, Moonshot and Groq.
Agent Memory Consolidation: What a Nightly "Dreaming" Job Should Do to Your Agent's Memory, and How to Check It Did
Agent memory consolidation is a background job that merges duplicate memories, supersedes replaced facts, expires time-bound ones and promotes repeated episodes into durable facts. Run it on a copy, verify the copy against invariants and known answers, then swap. How Anthropic Dreams, Letta and Mem0 Dream do it, the failure modes of unattended runs, and a tested Python job.
Fireworks AI vs Together AI Pricing 2026: Same Models Side by Side, Cached Input, Batch, GPUs, Fine-Tuning and Cost per Conversation
Fireworks AI vs Together AI pricing as of 29 October 2026: identical list prices on Kimi K3, GLM 5.3, DeepSeek V4.1 Flash, Muse Spark Open and four more shared models, but GPT-OSS 120B cached input at $0.015 on Fireworks and no cached rate on Together, a 50% batch discount on Fireworks against one discounted batch model on Together, H100s at $8.00 an hour against $5.49, cheaper fine-tuning on Together, a $1 credit against a $15 minimum, and what a 40-turn conversation costs on each.
GLM 5.2 API Pricing 2026: GLM-5.2, GLM-5.3 and Every Z.ai Model per Million Tokens, Cache, Free Models, Coding Plan and Cost per Conversation
GLM 5.2 API pricing as of 29 October 2026: $1.40 input, $0.26 cached input and $4.40 output per million tokens on Z.ai, the same as the newer GLM-5.3 that replaced it as Zhipu's flagship in August. Every current GLM model in USD and on bigmodel.cn in CNY, free Flash models, how the automatic cache bills, the Coding Plan's credits and what they mean for API users, open-weight hosts from Together to DeepInfra, and what a 40-turn conversation costs next to Kimi, Qwen, DeepSeek, Groq, Gemini and Claude.
Qwen API Pricing 2026: Every Qwen Model per Million Tokens on Alibaba Cloud, by Region, Free Quota, Cache, Batch and Cost per Conversation
Qwen API pricing per million tokens as of 29 October 2026: Qwen3.8-Max at $2 input and $6 output on Alibaba Cloud Model Studio's Singapore region and $1.65 and $4.95 on Global-scope rows, Qwen3.7-Plus at $0.40 and $1.60 (20% off for now), Qwen3.8-Flash at $0.15 and $0.47, Qwen3.7-Flash from $0.03 and $0.13, 1 million free tokens per model, context tiers, cache and Batch rules, CNY prices, where open-weight Qwen runs cheaper, and what a 40-turn conversation costs next to DeepSeek, Groq, Gemini and Claude.
MCP Memory Server: What the Protocol Standardises, What It Leaves to the Backend, and How to Choose or Build One
An MCP memory server is an ordinary MCP server whose tools read and write memory. The 2026-07-28 spec standardises tool discovery, tool annotations, resources and subscriptions, stdio and Streamable HTTP, and OAuth 2.1 for remote servers. It says nothing about extraction, conflicting facts, scoping, deletion or staleness. What each side owns, what the official reference server does and where it stops, and how to choose or build one, read from the spec and each project's docs on 29 October 2026.
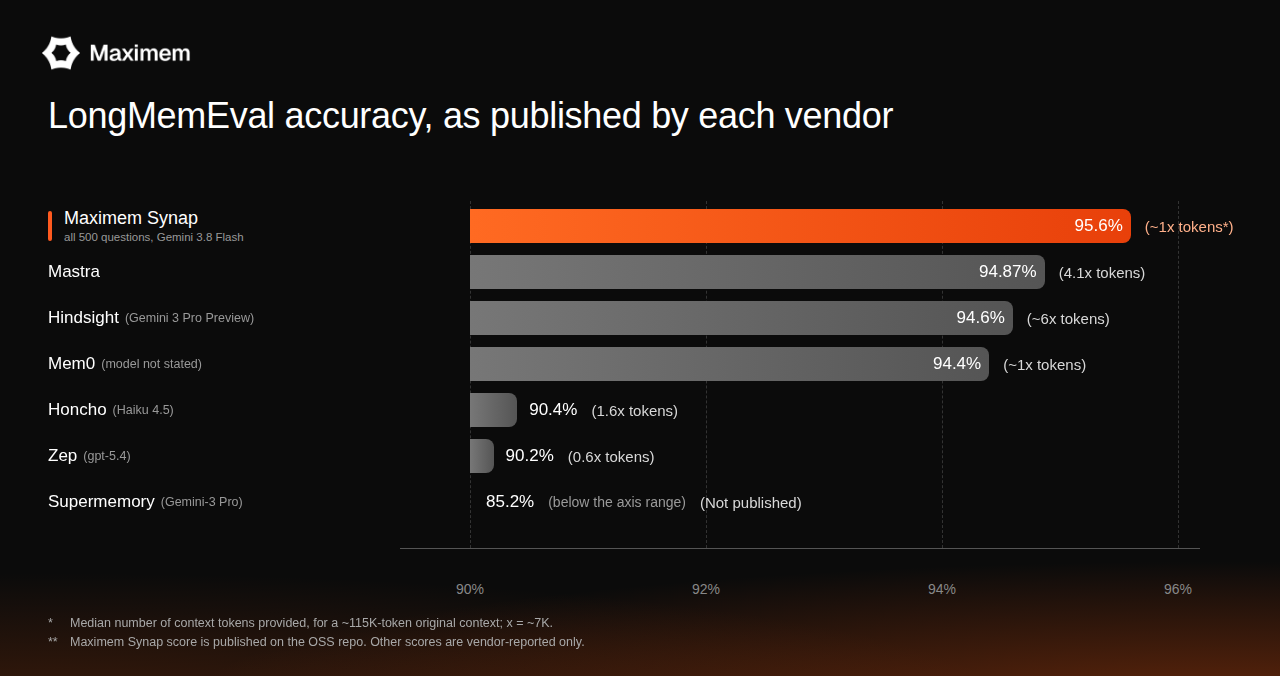
Synap Is #1 on LongMemEval: 95.6% on All 500 Questions
Maximem Synap is #1 on LongMemEval: 95.6% on all 500 questions with Gemini 3.8 Flash, at about 7.4K tokens per question. Every answer and verdict is public.
AI Agent Deprovisioning: Revoking Access Does Not Erase What the Agent Remembered
Revoking an AI agent's OAuth token, removing a tool permission or offboarding a user stops the next read, but the summaries, embeddings, cached tool results and shared team memory the agent already wrote stay readable. What an offboarding checklist has to cover for memory: which of three revocation events you are handling, memory scoped to the credential it came through, provenance on every derived fact, permission checks at read time, purge on revocation, and an audit record that proves it.
Kimi K3 API Pricing 2026: K3, K3.1 Pro and Every Kimi Model per Million Tokens, Cache Writes, Limits and Cost per Conversation
Kimi K3 API pricing as of 30 October 2026: $3.00 input, $0.30 cached input and $15.00 output per million tokens on Moonshot's platform, while the newer Kimi K3.1 Pro costs less at $2.00, $0.20 and $10.00. Every current Kimi model in USD and CNY, the new 5-minute and 1-hour cache writes, rate-limit tiers, what Together, Fireworks, DeepInfra and OpenRouter charge, and what a 40-turn conversation costs next to DeepSeek, Mistral, Groq, Gemini and Claude.
Multi-Agent Shared Memory: What Agents Should Share, How to Scope It, and How One Agent Poisons the Rest
Shared memory for a team of AI agents is a write-governance problem, not a storage problem. What to share and keep private, how it differs from orchestration state and handoffs, why scoping memory before retrieval beats one global history, how to scope it per agent, run, user and tenant, how to handle conflicting writes, what provenance to record, and what October 2026 studies from DeepMind, Meta and MIT Media Lab show about shared notes, poisoned notes and rejections that fall out of the context window.
How Do You Prevent Memory Poisoning Attacks on AI Agents?
How to prevent memory poisoning in AI agents: the five ways poisoned content gets into memory, the published attacks on ChatGPT, Bedrock Agents and Claude Code, what OWASP ASI06 requires, eight defences from write-path validation to rollback, which ones still hold when the model is fooled, and a test plan you can run in CI.
How Do You Make AI Agent Memory GDPR Compliant? Erasure That Reaches Derived Facts, Embeddings and Backups
AI agent memory is personal data, so GDPR applies to every fact, summary and embedding it keeps. What compliance takes in practice: a lawful basis per memory purpose, minimisation on the write path, retention limits, erasure that reaches derived facts, embeddings and backups, access and portability exports, processor contracts with the memory vendor and the LLM provider, transfer safeguards, a DPIA where risk is high, and where the EU AI Act fits after the July 2026 changes. Read against the GDPR text and EDPB guidance on 28 October 2026.
How Do You Add Episodic and Semantic Memory to an AI Agent? A Working Python Build With SQLite, Local Embeddings and Tests
Add episodic and semantic memory to an AI agent with two SQLite tables and two code paths: episodes record what happened and when, facts hold what is true now and a new value closes the old one, a write path extracts both after each session, and a read path ranks them into the prompt. A shared playbook table, changed only on evidence attributed to the strategy as in Alibaba's SPAR, carries what works across users. Full Python with local embeddings, thirteen passing tests, no API key.
Claude Code Memory, Codex Memory and Cursor Memory: What Each Coding Agent Remembers Between Sessions, Where It Lives, and How to Share It
Claude Code remembers through CLAUDE.md and auto memory (the first 200 lines or 25KB of MEMORY.md), Codex through AGENTS.md (32 KiB by default) and opt-in local Memories, and Cursor through Rules and AGENTS.md since it removed Memories in 2.1. Where each one stores memory, what each forgets, and how to make one memory persist and be shared across all three, read from each vendor's docs on 28 October 2026.